Test the Text the Model Actually Receives
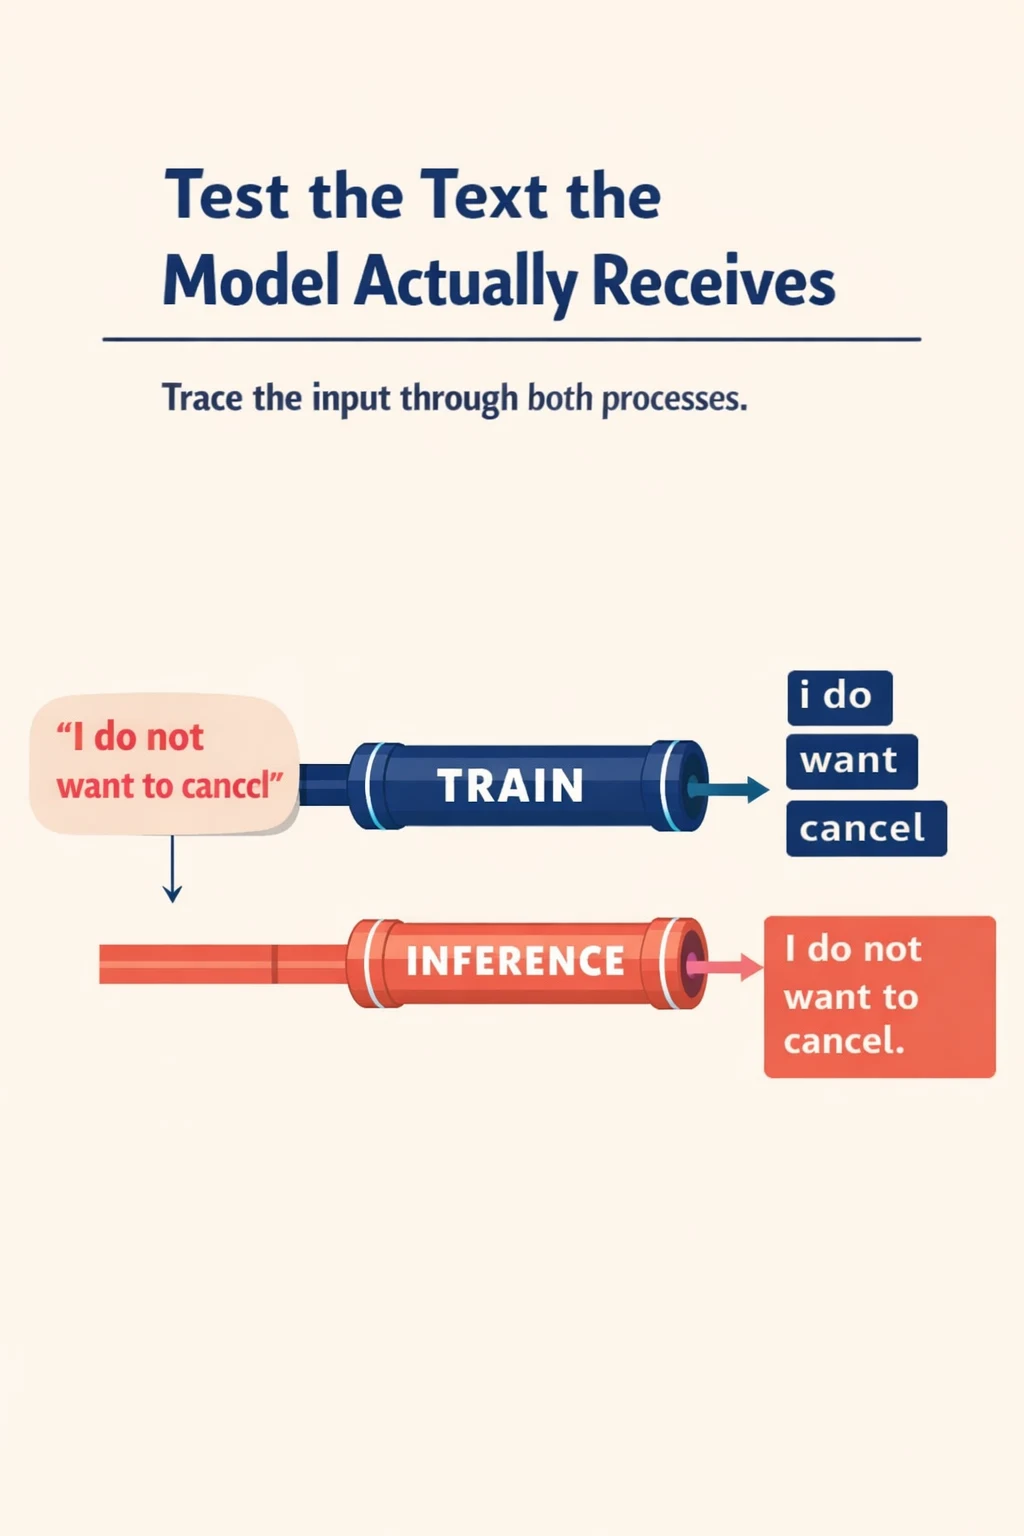
A model can be tested on one text and receive a different representation in another part of the workflow. Here’s a hypothetical NLP check—not a report of measured results.
1 — Trace the input. For the same examples, compare the raw text, normalized text, and tokenized or truncated input used in training and inference.
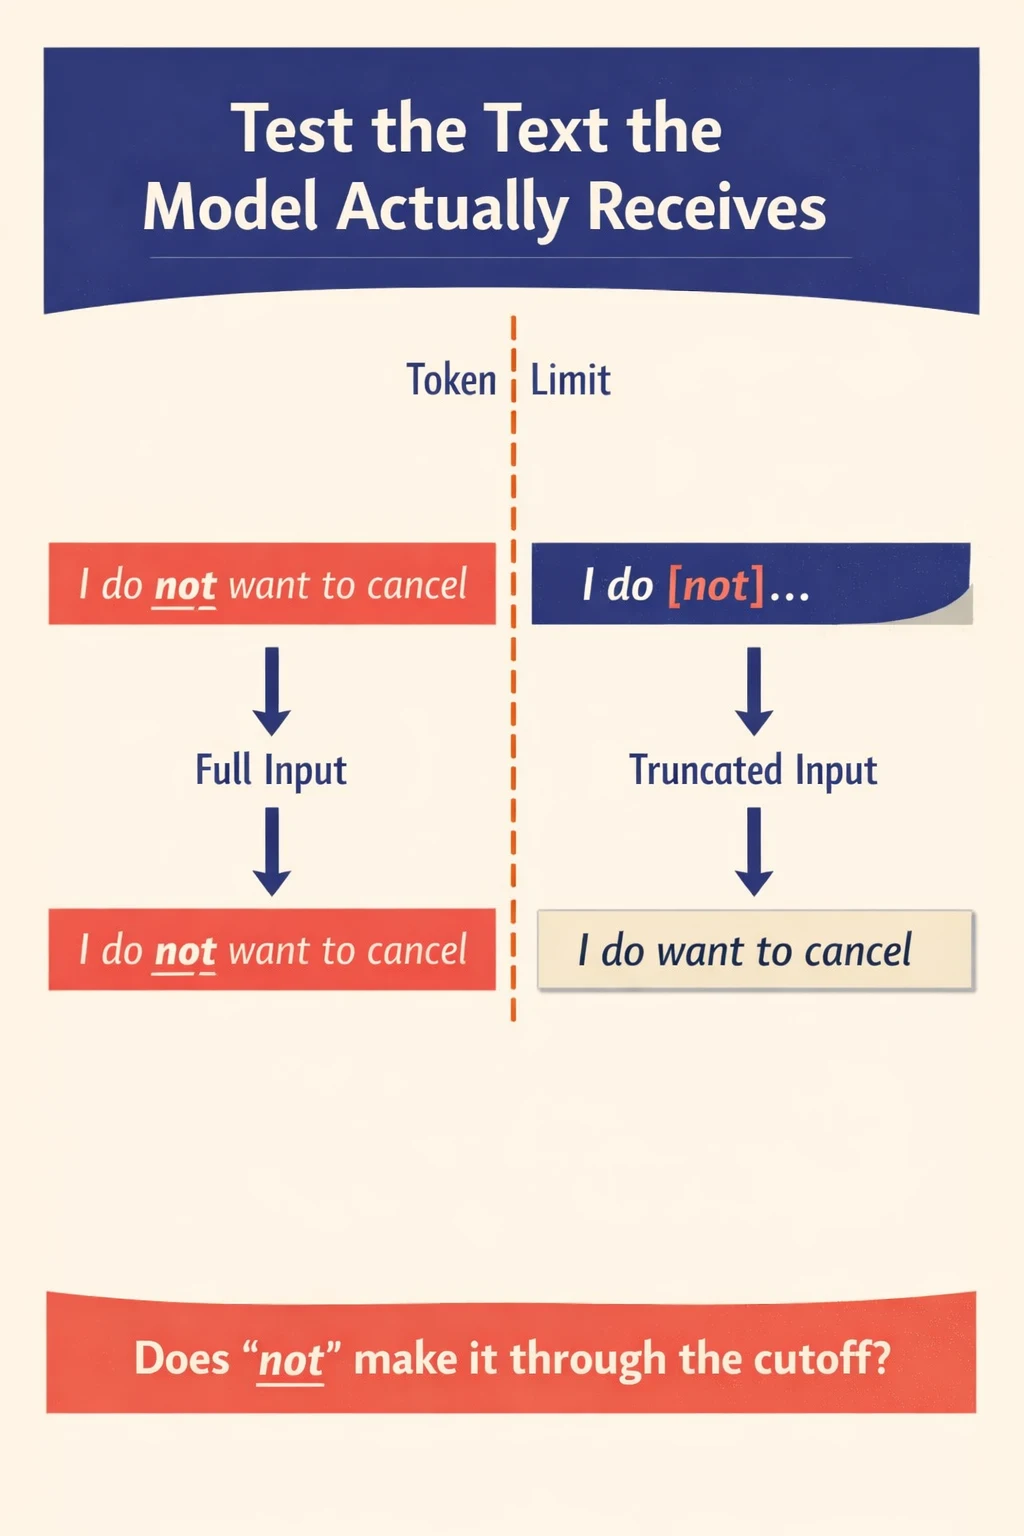
2 — Test a boundary case. Try a fictional sentence such as “I do not want to cancel,” with “not” near the model’s input-length limit. If one path drops it and the other keeps it, investigate the mismatch before interpreting a prediction. Add examples just before and after the truncation boundary.
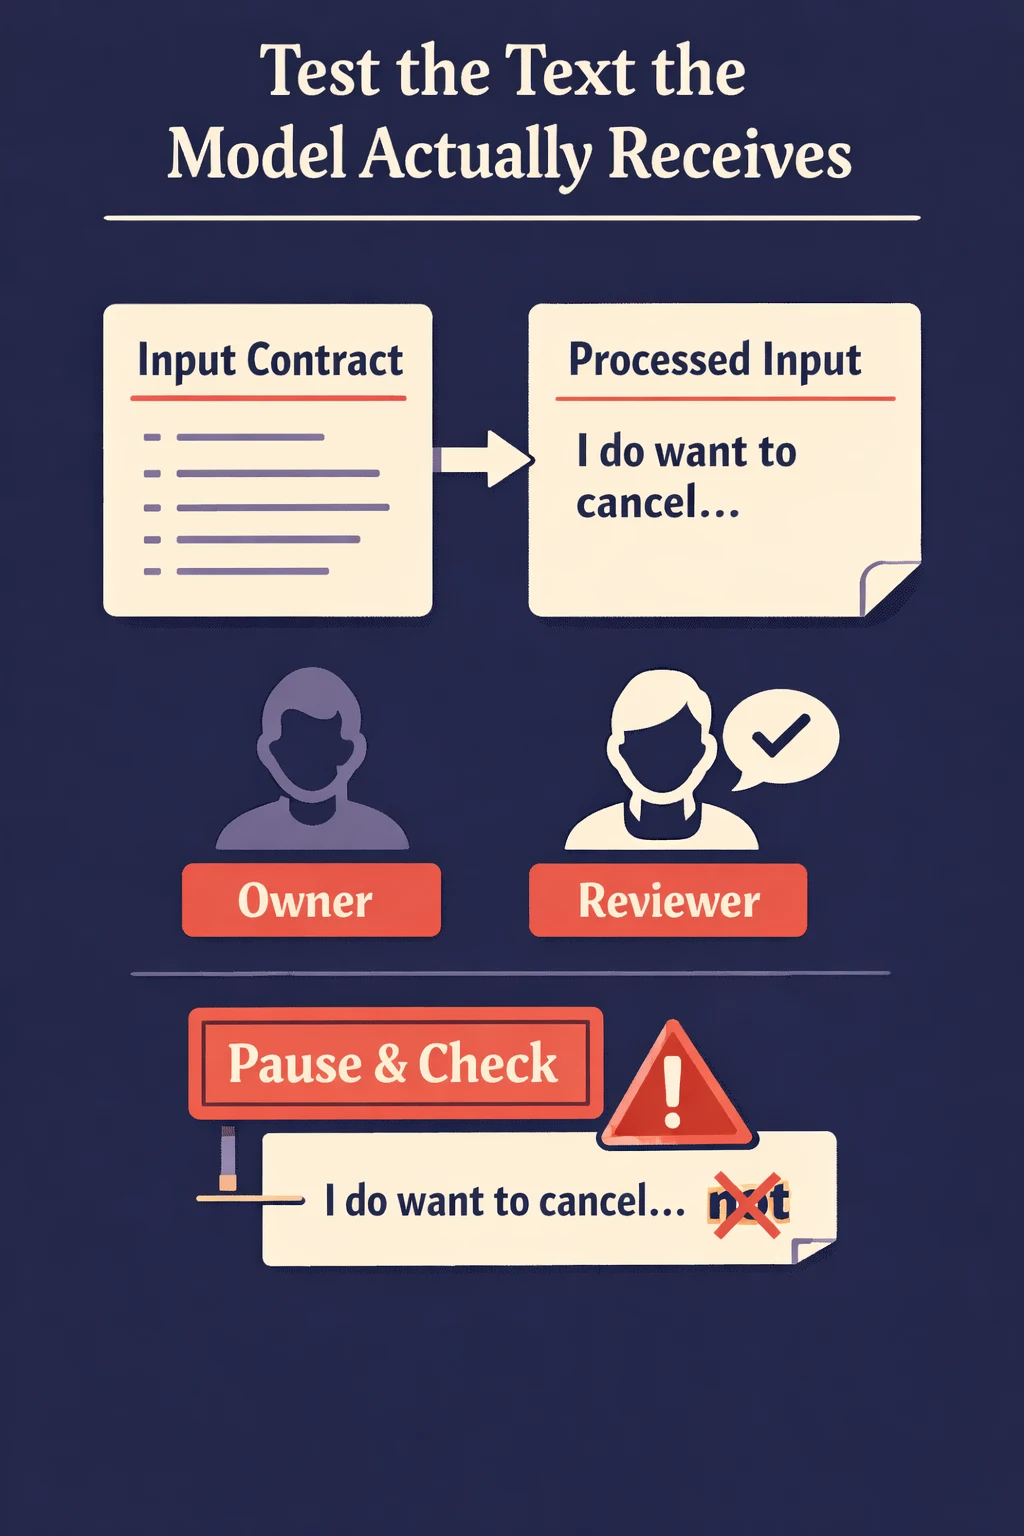
3 — Make the contract explicit. Record the preprocessing and tokenizer versions. Agree who owns that input contract, who needs to review changes, and what mismatch should trigger a pause and investigation.
Which input transformation would you compare first in an NLP workflow?