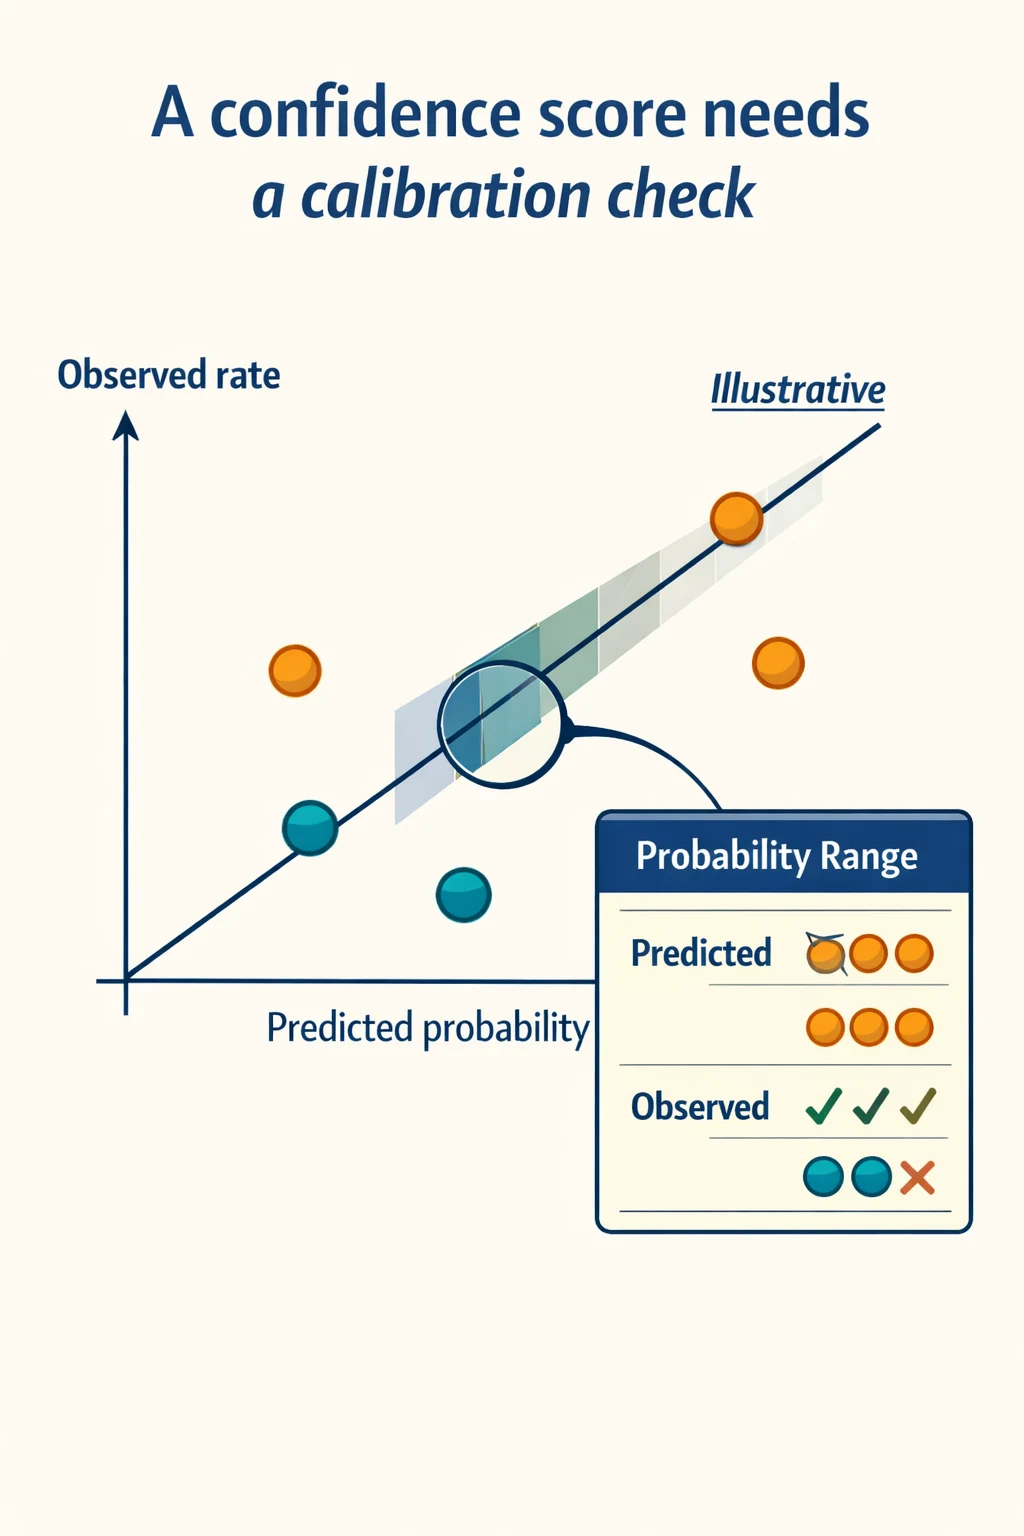
A confidence score needs a calibration check
A model can be accurate overall yet give confidence scores that are poorly calibrated. Calibration asks whether predictions made with a given probability are correct at about that rate over a suitable set of cases. For example, among cases assigned a probability near 0.8, roughly 80% should match the predicted outcome if those scores are well calibrated.
A hypothetical review exercise: group predictions into probability ranges, then compare each range’s average predicted probability with the observed outcome rate. Keep the sample size visible; a small set can make the comparison noisy. A calibration plot can help visualize the gaps.
Calibration does not decide what action a score should trigger. Before using it in a workflow, agree who owns that decision, who should be consulted, and what evidence would prompt a review.
This is an evaluation suggestion, not a result from a deployed model. Reference: scikit-learn, Probability calibration: https://scikit-learn.org/stable/modules/calibration.html
What decision would you want to make more carefully if a model’s confidence scores were better calibrated?